
Exposing LLM biases: Judging in isolation
After publishing
 Exposing LLM biases, I
got talking with people about the recommendation of judging one question at a time, with some
context duplicated across multiple LLM calls. That keeps the judgements fair, but it would
have a big impact on token usage and cost... or would it?
Forking an LLM judge into one call per question removes score bleed, but every fork repeats the initial prompt. We can structure the forks so the shared context is reused from the provider's cache, making the individual calls only marginally more expensive than a single combined call.
The setup
We reuse two mocktails from
Exposing LLM biases:
Sunset Fizz
and Berry Cooler, judging them
two ways:
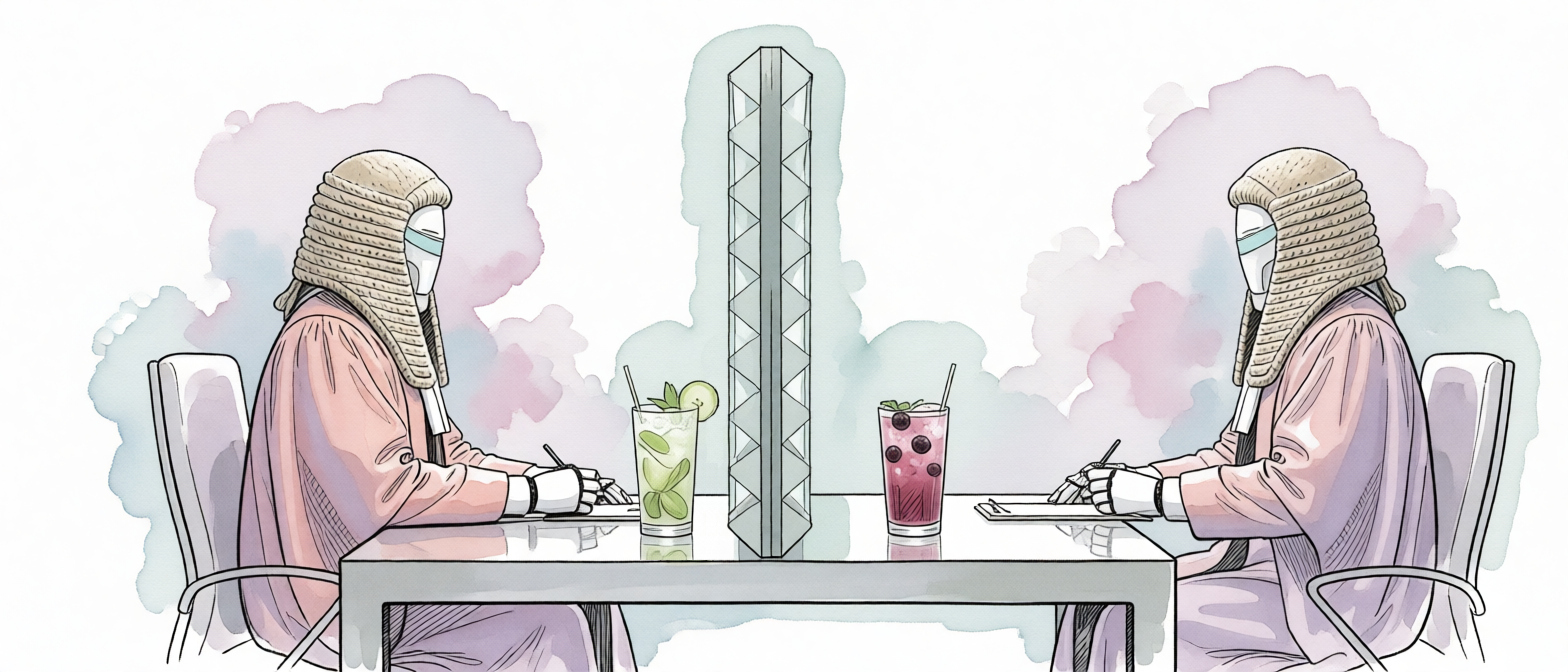
- Combined: Making a single call, asking to judge on both recipes at the same time.
- Isolated: Making two calls in sequence (you'll see why), each asking to judge a single recipe.
Show the combined conversation
You are evaluating two mocktail recipes. Score each recipe independently on overall quality.
Consider name creativity, flavour coherence, description appeal, and instruction clarity.

Use this rubric for each criterion.

Name creativity
- High (8–10): evocative and specific, hinting at flavour or mood, e.g. "Orchard Ember" for a spiced apple drink.
- Middle (4–7): accurate but generic, e.g. "Apple Spritz".
- Low (1–3): misleading, unappetising or unrelated to the drink, e.g. "Swamp Water" for a cucumber cooler.

Flavour coherence
- High (8–10): ingredients complement each other, with a clear balance of sweet, sour and aromatic elements, e.g. pineapple, lime and mint.
- Middle (4–7): workable but unbalanced, e.g. so much syrup that it masks the fruit, or an ingredient that adds nothing.
- Low (1–3): ingredients clash or would be unpleasant to drink, e.g. savoury brines or sauces in a sweet drink, or undrinkable proportions.

Description appeal
- High (8–10): one or two sentences that make the reader want the drink, naming its character and the occasion it suits.
- Middle (4–7): accurate but flat, listing ingredients without conveying taste or mood.
- Low (1–3): vague, missing or off-putting.

Instruction clarity
- High (8–10): steps in a sensible order, specific about technique (muddle, shake, stir, strain), glassware, ice and garnish, so a novice could follow them.
- Middle (4–7): mostly followable but missing a detail, such as the glassware or how much ice.
- Low (1–3): steps out of order, ambiguous, or missing key actions.

Weigh the four criteria equally.

Score from 1–10, where 1 is terrible, 5 is mediocre, and 10 is perfect.
Respond in JSON: {"recipe_1_score": <1-10>, "recipe_1_rationale": "<reasoning>", "recipe_2_score": <1-10>, "recipe_2_rationale": "<reasoning>"}Rate these two mocktail recipes:
## Recipe 1
```json
{
"name": "Sunset Fizz",
"description": "A warm citrus blend layered with fresh basil and topped with sparkling water, served over crushed ice as the light fades.",
"flavourProfile": "citrus, herbal, refreshing",
"ingredients": [
{
"item": "fresh orange juice",
"amount": 60,
"unit": "ml"
},
{
"item": "lime juice",
"amount": 15,
"unit": "ml"
},
{
"item": "fresh basil leaves",
"amount": 4,
"unit": "leaves"
},
{
"item": "simple syrup",
"amount": 10,
"unit": "ml"
},
{
"item": "soda water",
"amount": 120,
"unit": "ml"
}
],
"steps": [
"Muddle basil leaves gently with simple syrup in a rocks glass.",
"Add orange juice and lime juice, stir to combine.",
"Fill the glass with crushed ice.",
"Top with soda water.",
"Garnish with a basil sprig and orange wheel."
]
}
```
## Recipe 2
```json
{
"name": "Berry Cooler",
"description": "A bright berry blend with fresh mint and a hint of lime, served tall over ice.",
"flavourProfile": "berry, mint, tart",
"ingredients": [
{
"item": "mixed berry purée",
"amount": 80,
"unit": "ml"
},
{
"item": "fresh mint leaves",
"amount": 6,
"unit": "leaves"
},
{
"item": "lime juice",
"amount": 15,
"unit": "ml"
},
{
"item": "honey syrup",
"amount": 10,
"unit": "ml"
},
{
"item": "soda water",
"amount": 100,
"unit": "ml"
}
],
"steps": [
"Muddle mint leaves with honey syrup in a tall glass.",
"Add berry purée and lime juice, stir well.",
"Fill the glass with ice.",
"Top with soda water and stir gently.",
"Garnish with fresh berries and a mint sprig."
]
}
```{
"recipe_1_score": 9,
"recipe_1_rationale": "Name is evocative and specific, flavor combination of orange, lime, basil and soda is balanced and refreshing, description sets a pleasant sunset mood, and instructions are clear with glassware, ice, technique and garnish specified.",
"recipe_2_score": 7,
"recipe_2_rationale": "Name and description are accurate but generic, lacking the same evocative specificity. Flavor profile is coherent with berry, mint and lime, and instructions are clear, but the overall presentation is less distinctive."
}Show the isolated Sunset Fizz conversation
You are evaluating a mocktail recipe. Score the recipe on overall quality.
Consider name creativity, flavour coherence, description appeal, and instruction clarity.

Use this rubric for each criterion.

Name creativity
- High (8–10): evocative and specific, hinting at flavour or mood, e.g. "Orchard Ember" for a spiced apple drink.
- Middle (4–7): accurate but generic, e.g. "Apple Spritz".
- Low (1–3): misleading, unappetising or unrelated to the drink, e.g. "Swamp Water" for a cucumber cooler.

Flavour coherence
- High (8–10): ingredients complement each other, with a clear balance of sweet, sour and aromatic elements, e.g. pineapple, lime and mint.
- Middle (4–7): workable but unbalanced, e.g. so much syrup that it masks the fruit, or an ingredient that adds nothing.
- Low (1–3): ingredients clash or would be unpleasant to drink, e.g. savoury brines or sauces in a sweet drink, or undrinkable proportions.

Description appeal
- High (8–10): one or two sentences that make the reader want the drink, naming its character and the occasion it suits.
- Middle (4–7): accurate but flat, listing ingredients without conveying taste or mood.
- Low (1–3): vague, missing or off-putting.

Instruction clarity
- High (8–10): steps in a sensible order, specific about technique (muddle, shake, stir, strain), glassware, ice and garnish, so a novice could follow them.
- Middle (4–7): mostly followable but missing a detail, such as the glassware or how much ice.
- Low (1–3): steps out of order, ambiguous, or missing key actions.

Weigh the four criteria equally.

Score from 1–10, where 1 is terrible, 5 is mediocre, and 10 is perfect.
Respond in JSON: {"score": <1-10>, "rationale": "<reasoning>"}Rate this mocktail recipe:
```json
{
"name": "Sunset Fizz",
"description": "A warm citrus blend layered with fresh basil and topped with sparkling water, served over crushed ice as the light fades.",
"flavourProfile": "citrus, herbal, refreshing",
"ingredients": [
{
"item": "fresh orange juice",
"amount": 60,
"unit": "ml"
},
{
"item": "lime juice",
"amount": 15,
"unit": "ml"
},
{
"item": "fresh basil leaves",
"amount": 4,
"unit": "leaves"
},
{
"item": "simple syrup",
"amount": 10,
"unit": "ml"
},
{
"item": "soda water",
"amount": 120,
"unit": "ml"
}
],
"steps": [
"Muddle basil leaves gently with simple syrup in a rocks glass.",
"Add orange juice and lime juice, stir to combine.",
"Fill the glass with crushed ice.",
"Top with soda water.",
"Garnish with a basil sprig and orange wheel."
]
}
```{
"score": 9,
"rationale": "Name is evocative and specific, pairing 'Sunset' with basil and fizz. Flavour profile is coherent: orange, lime, basil, and soda balance citrus, herbal, and refreshing notes, with simple syrup adding light sweetness. Description is appealing and sets a clear mood/occasion. Instructions are clear and mostly complete, specifying muddling, stirring, glassware, ice, and garnish; only minor detail like expressing the basil garnish could improve it further."
}
We'll use
deepseek/deepseek-v4.1-flash,
through OpenRouter, pinned to the Together provider. Together suits us well, due to its
support for structured JSON responses and support for input token caching.
Where the tokens go
Here's how the "combined" and "isolated" calls compare, averaging the tokens per call over 20 trials. This example also beefs up the system prompt to include a reusable scoring rubric with examples, followed by guidance on how to format the JSON output.
Input
- System prompt
- User prompt
- Cached input
Output
- Reasoning
- Response
-
The combined call judges
Sunset Fizz and
Berry Cooler together (1,055
input + 880 output = 1,935 total):
- The system prompt asks for two scores.
- The user prompt provides two recipes, and the reasoning and response cover judgement of both recipes.
-
The first isolated call judges
Sunset Fizz alone (746 input +
481 output = 1,227 total):
- The system prompt has the same rubric, but asks for one score, so it's slightly shorter.
- The user prompt and reasoning each cover one recipe, so each is about half the size. The response shrinks less, because part of it is JSON structure.
-
The second isolated call judges
Berry Cooler alone (749 input
+ 438 output = 1,187 total):
- The system prompt is identical to the one from the previous call. The provider can only reuse a prompt it has already seen, so running this call second means most of the system prompt comes from the cache.
- The user prompt, reasoning and response each cover one recipe, as above.
Let's break down the costs, using
OpenRouter's pricing
for
deepseek/deepseek-v4.1-flash on
Together as of 2026-10-06:
- The combined call uses 1,935 tokens, so making the call a thousand times costs USD1.37.
- The two isolated calls use 2,414 tokens between them; 25% more tokens. But not all tokens cost the same.
- Input tokens cost 25% of the output token price. A thousand pairs of isolated calls would cost USD1.55, only 13% more.
- Cached input costs 2% of the regular input price. With caching, a thousand pairs of isolated calls cost USD1.44, just 5% more than the combined calls.
Show the numbers
| Call | System | Cached | User | Reasoning | Response | Total | Cost |
|---|---|---|---|---|---|---|---|
| Combined (Both recipes) | 509 | 0 | 546 | 700 | 181 | 1,935 | USD0.00137 |
| Isolated (Sunset Fizz) | 477 | 0 | 269 | 375 | 106 | 1,227 | USD0.00080 |
| Isolated (Berry Cooler) | 477 | 384 | 272 | 336 | 102 | 1,187 | USD0.00064 |
Prices per million tokens: USD0.30 input, USD0.006 cached input, USD1.20 output.
What isolation changes
Each isolated call sees only one recipe, so nothing else in the context can pull its score up or down. Combined, Sunset Fizz averages 8.9 and Berry Cooler averages 7.0. Isolated, they average 8.6 and 7.3, so the gap between them narrows once neither recipe sets the bar for the other.
In conclusion
Making a separate LLM call for each judgement makes each one fairer, and with the shared prompt cached, it costs only a little more than judging both together. To benefit the most from this, you should:
- Check that your provider caches. Not every provider does, so look for
cached_tokensin the usage data of your follow-up calls. - Put the shared parts first. Structure your prompts so the system prompt focuses on repeated content, and the user prompt progresses into into dynamic content.
- Warm the cache before you fan out. Wait for the first call to finish before running the next calls in parallel, to ensure reuse of the cached tokens.
This article belongs to Exposing LLM biases.
If you have feedback or questions about this article, let's catch up via
LinkedIn or email.
 All articles
 About Sinclair Studios